TL;DR
Regulated document intelligence is AI that reads your compliance documents, then proves the data is right. It checks every field against the rules your regulator cares about, links each value back to the page it came from, sends anything odd to a named person, and records who approved what. Plain extraction stops at reading. If an auditor can ask “where did this number come from?”, you need the other half too.
Somewhere in your business there is an archive box. It is labelled AUDIT STUFF (DO NOT THROW OUT), it lives under a desk, and nobody remembers what’s in it.
It’s your compliance system. [Gently pats the box.]
This article is about what replaces that box. It isn’t one more app that “reads PDFs with AI”, because plenty of tools can read a PDF now.
The hard part, in a regulated business, is everything that has to happen after the reading.
Here’s what this guide covers: what regulated document intelligence is, how it differs from OCR and ordinary extraction, the five checks it runs, and what it looks like on a real kind of file. Plus what should stay with a person, and the mistakes worth skipping. One archive box will be harmed in the making of this article.
Got a box like that?
Find out which of your documents are worth automating first
A Pain Point Audit maps how your compliance paperwork actually moves today, then ranks what should be read, checked and recorded automatically. You get a written report in plain English.
On this page
- What is regulated document intelligence?
- How is regulated document intelligence different from OCR and plain extraction?
- The five checks behind every build
- Why do regulated industries need more than extraction?
- A worked example: one building permit file, before and after
- What gets automated, where AI helps, and what stays human
- Is regulated document intelligence worth it?
- Common mistakes with compliance documents and AI
- Lumeio’s recommendation on regulated document intelligence
- Frequently asked questions
What is regulated document intelligence?
Regulated document intelligence is document automation built for businesses that answer to a regulator. AI reads PDFs, scans, photos and forms into structured data. Rules then validate each field against your obligations, every value links back to its source page, exceptions go to a named reviewer, and every step lands in an audit trail.
That’s the whole idea in one breath. The word doing the heavy lifting is “regulated”.
In an ordinary business, a wrong field on an invoice is annoying. In a regulated one, a wrong waste code, an expired insurance certificate or a missing screening record can become a finding, a fine or a very long afternoon with an auditor.
So the job isn’t just “turn this PDF into data”. The job is “turn this PDF into data you can defend”.
At Lumeio we use the term for the work we do in waste and EPA compliance, aged care, building surveying, construction and accounting. Different regulators, different paperwork. The same five checks underneath.
How is regulated document intelligence different from OCR and plain extraction?
OCR turns an image into text, and extraction turns text into labelled fields. Regulated document intelligence adds the part regulators actually ask about: checking the fields against rules, keeping a link to the source page, routing exceptions to a person and logging every decision. It is extraction plus proof.
Think of it as three people at the same desk.
OCR is the person who can read every word on the page and has no idea what any of it means. Extraction is the person who can tell you “this is the invoice number, this is the total”. The third is the person who says “this total doesn’t match the purchase order, here’s the page, I’ve sent it to Priya, and I wrote all of that down”.
If you want the technology side in more depth, our guide to document AI vs OCR walks through where each one stops.
| Question an auditor asks | OCR | Plain extraction | Regulated document intelligence |
|---|---|---|---|
| What does the document say? | Yes, as text | Yes, as fields | Yes, as fields |
| Is the data correct? | No | Sometimes, if you check | Checked against your rules |
| Where did this value come from? | No | Rarely | One click to the source page |
| Who looked at the odd ones? | No | No | A named reviewer, timestamped |
| Can you show me the history? | No | No | Full history, logged |
Notice the first row is the only one most tools brag about.
The five checks behind every build
Every build runs each document through the same five steps. Some are pure rules, one uses AI, one is a person, and one is just very good record keeping.
- ReadAI pulls the fields out of the PDF, scan, photo or form, whatever the layout.AI
- ValidateRules check each field: right code, valid date, totals that tie, details that match across documents.Automation
- TraceEvery value keeps a link to the exact page and spot it came from.Automation
- EscalateAnything that fails a rule goes to a named person with the reason attached.Human
- RecordEvery read, check, edit and approval is logged with who and when.Automation
Step one gets all the attention. Steps two to five are where the compliance value lives.
Read: the part everyone demos
Modern AI is genuinely good at reading messy documents. It copes with twelve supplier layouts, handwriting on a delivery docket and a phone photo taken at an angle that suggests the photographer was falling over.
But reading isn’t knowing. AI will read a smudged 7 as a 1 with total confidence. That’s why step two exists.
Validate: document validation against your rules
Document validation means checking every extracted field against something you already trust. That might be a list of approved waste codes, a supplier’s purchase order, a licence register, or the expiry date on an insurance certificate.
This is deterministic automation, not AI. The rules are written down, they run the same way every time, and they can be tested. When a regulator asks how you know the data is right, “the rules checked it” is a far better answer than “the AI seemed confident”.
[Confession.] I have a favourite date format. It’s the one where the year goes first, and validation rules are where that opinion finally becomes useful, because so many date errors are just the day and the month swapping places.
Trace: provenance for every value
Tracing means every value in your register keeps a pointer back to the source document and page. Click the number, see the scan.
It sounds small. It’s the difference between a five-second audit question and a five-hour hunt through shared drives.
Escalate: exceptions go to a person, by name
When a document fails a rule, it doesn’t vanish into a “review queue” that nobody owns. It goes to a named person, with the reason it failed and the source page attached.
This is human in the loop done properly. The person isn’t re-checking 400 documents. They’re deciding on the 20 that genuinely need judgement.
Record: the audit trail
An audit trail is the log of everything that happened to a document. When it arrived, what was read, which rules passed or failed, who changed a value and why, and who signed off.
Your archive box has no audit trail. It has a smell, and at least three date formats.
[Sniffs. Regrets it.]
Why do regulated industries need more than extraction?
Regulated industries need more than extraction because regulators don’t ask whether you read a document. They ask whether the record is complete, correct, kept for the right period and provable. Extraction gives you data. Validation, tracing and logging give you the evidence behind it.
[Switches to serious face.] Here’s what that looks like for some of the industries Lumeio works with. These are not legal advice, and each obligation has more detail on the regulator’s own page.
| Industry | Typical compliance documents | What the regulator expects |
|---|---|---|
| Waste and EPA | Weighbridge dockets, waste transport certificates | Reportable priority waste must be recorded in EPA Victoria’s Waste Tracker from generation to disposal, and each missing or incomplete record is a separate offence |
| Aged care | Care notes, incident records, worker screening | Former providers must keep certain records for 7 years after they stop being registered |
| Accounting | Client identity documents, AML/CTF checks | Accounting is one of the newly regulated sectors under AML/CTF laws, and AUSTRAC says records are usually kept for 7 years |
| Any business | Invoices, receipts, payroll records | The ATO sets a general 5-year retention period, with some records kept longer |
Look at the right-hand column. None of it says “read the PDF”. All of it is about completeness, correctness and keeping proof for years.
There’s an AI angle too. The federal government’s Guidance for AI Adoption asks organisations to maintain human oversight of AI systems and keep clear records of testing, incidents and monitoring. A build with named reviewers and full logging already does both.
And if your documents hold personal information, there’s one more date to know. From 10 December 2026, the OAIC says privacy policies must disclose where a computer program makes or informs decisions that significantly affect people. Our Privacy Act ADM checklist helps you work out whether that applies.
A worked example: one building permit file, before and after
This is an illustrative scenario with round numbers, not a client result. It shows how the five checks change one real kind of work.
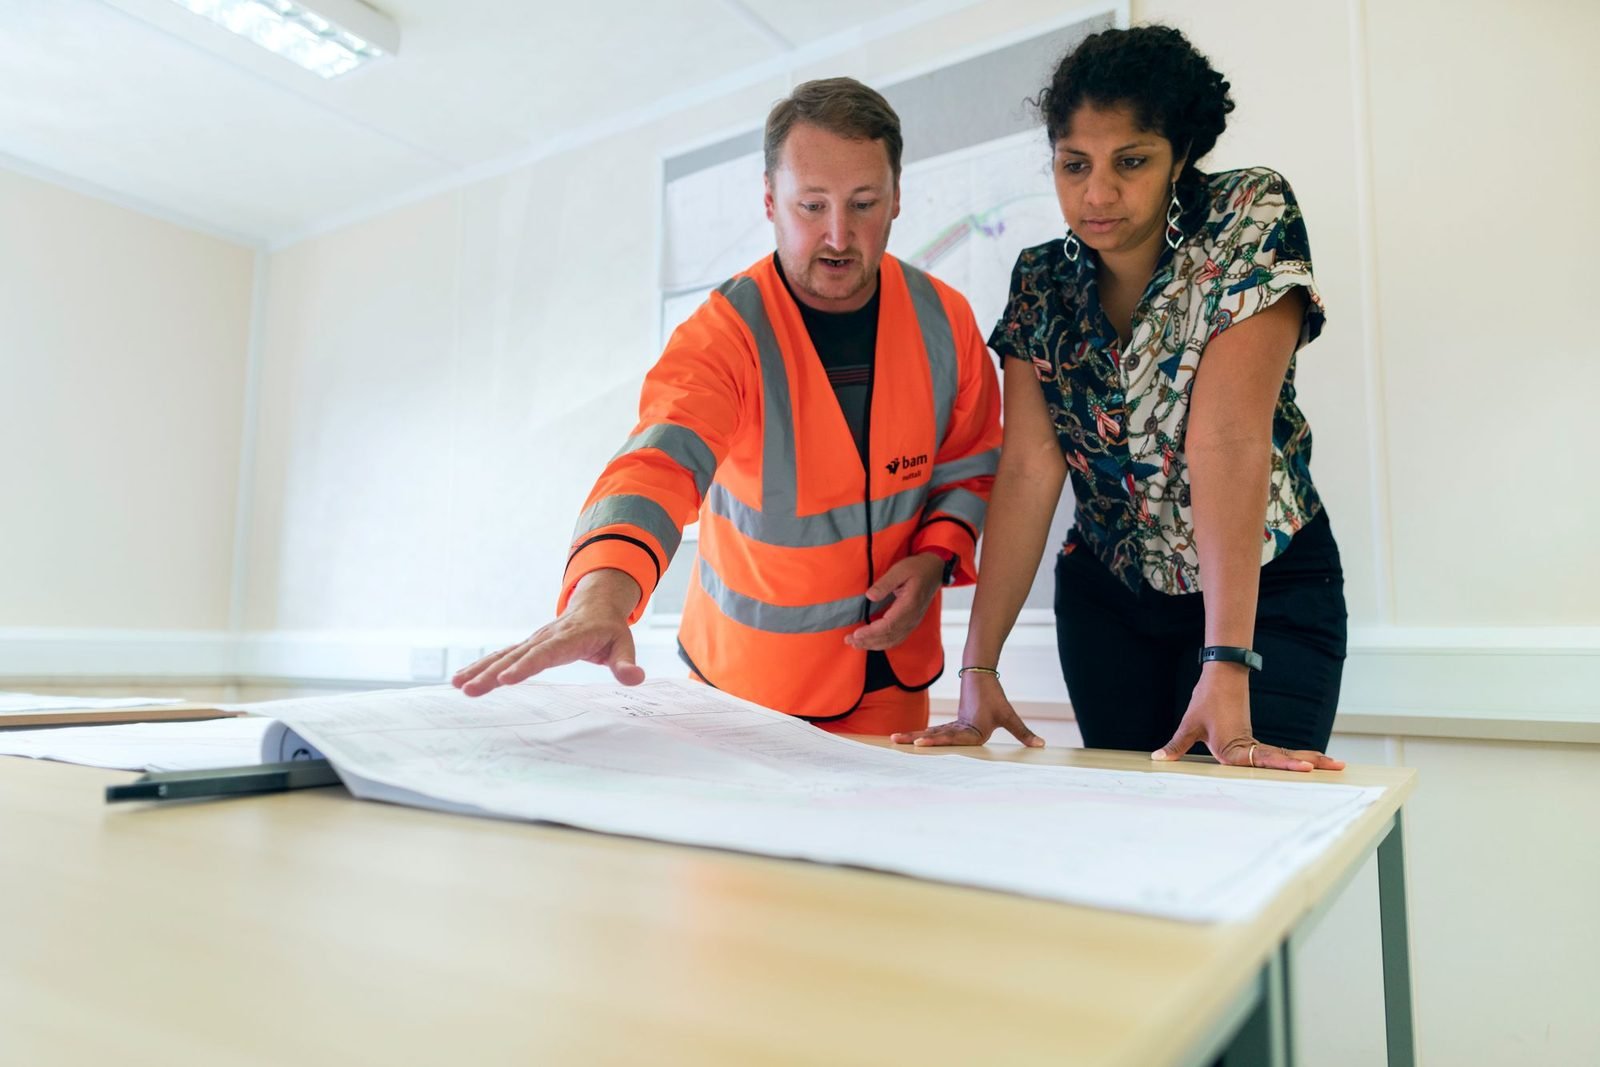
A building surveying practice opens about 15 new permit files a week. Each file arrives as a bundle: the application, drawings, an engineer’s certificate, a builder’s registration, insurance, and a few emails with attachments named “scan0042.pdf”.
Before anything else happens, someone checks the bundle. Is everything there?
Do the owner’s name, the address and the lot number match across every document? Is the insurance current? Is the engineer’s certificate for this job and not the one next door?
That check takes about 40 minutes a file. It’s careful, important work, and it is also mostly comparing one piece of paper to another piece of paper.
| Step | Before | After |
|---|---|---|
| Documents arrive | Email attachments, saved by hand | Read on arrival, filed to the permit |
| Completeness check | Someone ticks a paper checklist | Missing documents flagged automatically |
| Cross-document match | Name, address and lot compared by eye | Rules compare every field across the bundle |
| Expiry dates | Checked if someone remembers | Expired or soon-expiring items flagged |
| Exceptions | Found later, sometimes much later | Sent to the surveyor with the page attached |
| Record of the check | A ticked checklist in the file | A timestamped audit trail per document |
| Time per file | About 40 minutes | About 10 minutes, mostly exceptions |
The surveyor still makes every professional decision. What disappears is the comparing.
If you want to see this specific workflow in more detail, here’s how we approach building permit data extraction. The same pattern works for an aged care evidence pack, where care notes and incident records become audit evidence that staff sign off.
What gets automated, where AI helps, and what stays human
The fastest way to lose trust in a compliance build is to automate the wrong part. So here’s the split we use.
Automation and AI handle this
Predictable, checkable, and happy to work at 2am. – Reading fields from PDFs, scans and photos (AI) – Classifying what kind of document arrived (AI) – Checking codes, dates, totals and matches (rules) – Linking every value to its source page (rules) – Logging every step to the audit trail (rules)
A person keeps this
Judgement, accountability and anything a regulator would ask a person about. – Deciding what to do with an exception – Approving anything with legal or safety weight – Signing off the record before it’s submitted – Talking to the client, resident or regulator
Notice where AI sits. It reads and classifies, because those are the jobs where documents are messy and rules can’t cope. Everywhere the answer must be the same every time, plain rules do it.
The one rule worth remembering. AI reads, rules check, people decide. If a build lets AI do the deciding on a regulated record, walk away.
Is regulated document intelligence worth it?
Regulated document intelligence is worth it when you handle enough of the same document type to repeat the checking every week, and when an error has a real cost. It usually isn’t worth it for a few dozen documents a month, or when the data already exists in a system you can export from.
Back to the permit file. Saving 30 minutes on each of 15 files a week returns about 7.5 hours a week.
Indicative opportunity, illustrative scenario only
About $15,500A year of skilled time returned from comparing paperwork, before you count a single avoided finding.
That assumes $45 an hour and 46 working weeks, the conservative figures from our guide to the ROI of AI automation. Your number depends on your volumes, your exception rate and how messy your documents are. That’s why we measure it from your own files before anyone quotes a build.
The money is rarely the main reason, though. The main reason is that the next audit question takes five seconds instead of a week. [Gives the archive box a meaningful look.]
Common mistakes with compliance documents and AI
We’d rather you avoid these than pay someone to fix them later.
- Trusting extraction without validation. Confident AI is still sometimes wrong. Every regulated field needs a rule behind it.
- Starting with the hardest document. Pick the high-volume, consistent document first. Handwritten oddities can wait.
- Re-checking everything anyway. If staff still review all 400 documents, you’ve bought an expensive second opinion. Exceptions only.
- A review queue with no owner. “The team” is not a reviewer. A named person is.
- No retention plan. An audit trail you delete after a year doesn’t help with a 7-year record keeping obligation.
- Forgetting where the data goes. Know which models read your documents, where the data is stored and who can see it, before anything is built.
That last one matters more than it sounds. On the document intelligence service page we explain how the audit report sets out storage, models and access for your approval before the build starts.
Lumeio’s recommendation on regulated document intelligence
Start with one document type and one rule that matters.
Pick the document your team handles most often, where a mistake would actually hurt. Write down what “correct” looks like for its three most important fields. If nobody can agree on that, software can’t check it either, and you’ve just found your first problem (congratulations, genuinely).
Then build regulated document intelligence around that one document: read, validate, trace, escalate, record. Prove it on real files. Expand once the exceptions are boring.
What we wouldn’t do is buy a general “AI document platform” and hope compliance falls out of it. The reading is the easy half. The proof is the half your regulator cares about.
Reading a document is a demo. Proving it is a system.
AI reads, rules check, people decide, and everything gets written down.
Got a compliance document your team checks by hand every week? Show us how it runs today. We’ll tell you honestly whether it’s worth automating.
Frequently asked questions
What does regulated document intelligence mean?
Regulated document intelligence is document automation for businesses that answer to a regulator. AI reads documents into structured data, rules check the data against your obligations, each value links to its source page, exceptions go to a named person, and every step is recorded in an audit trail.
Is regulated document intelligence the same as intelligent document processing?
It builds on it. Intelligent document processing reads documents and extracts fields. Regulated document intelligence adds validation against regulatory rules, source tracing, named exception owners and a full audit trail, because regulated industries need to prove the data is right, not just capture it.
Does it replace compliance staff?
No. It removes the comparing, retyping and hunting, so compliance staff spend their time on exceptions and decisions. People still approve anything with legal, safety or financial weight, and they remain accountable for the record.
Which documents suit it best?
High-volume documents with consistent fields and clear rules work best first: dockets, certificates, invoices, permit bundles, screening records and identity checks. Rare, handwritten or highly variable documents are better left until the core workflow is proven.
How long does it take to set up?
It depends on the document and the rules. A single document type with a handful of well-defined checks is a much smaller job than a whole compliance register. The fastest path is to measure one workflow first, which is exactly what a Pain Point Audit does.
Your move
Think your compliance paperwork could prove itself?
Book a Pain Point Audit. We’ll map one regulated workflow with you, measure what it costs today, and tell you plainly what should be automated and what should stay human.